Tandem Training for Language Models
Tandem Training
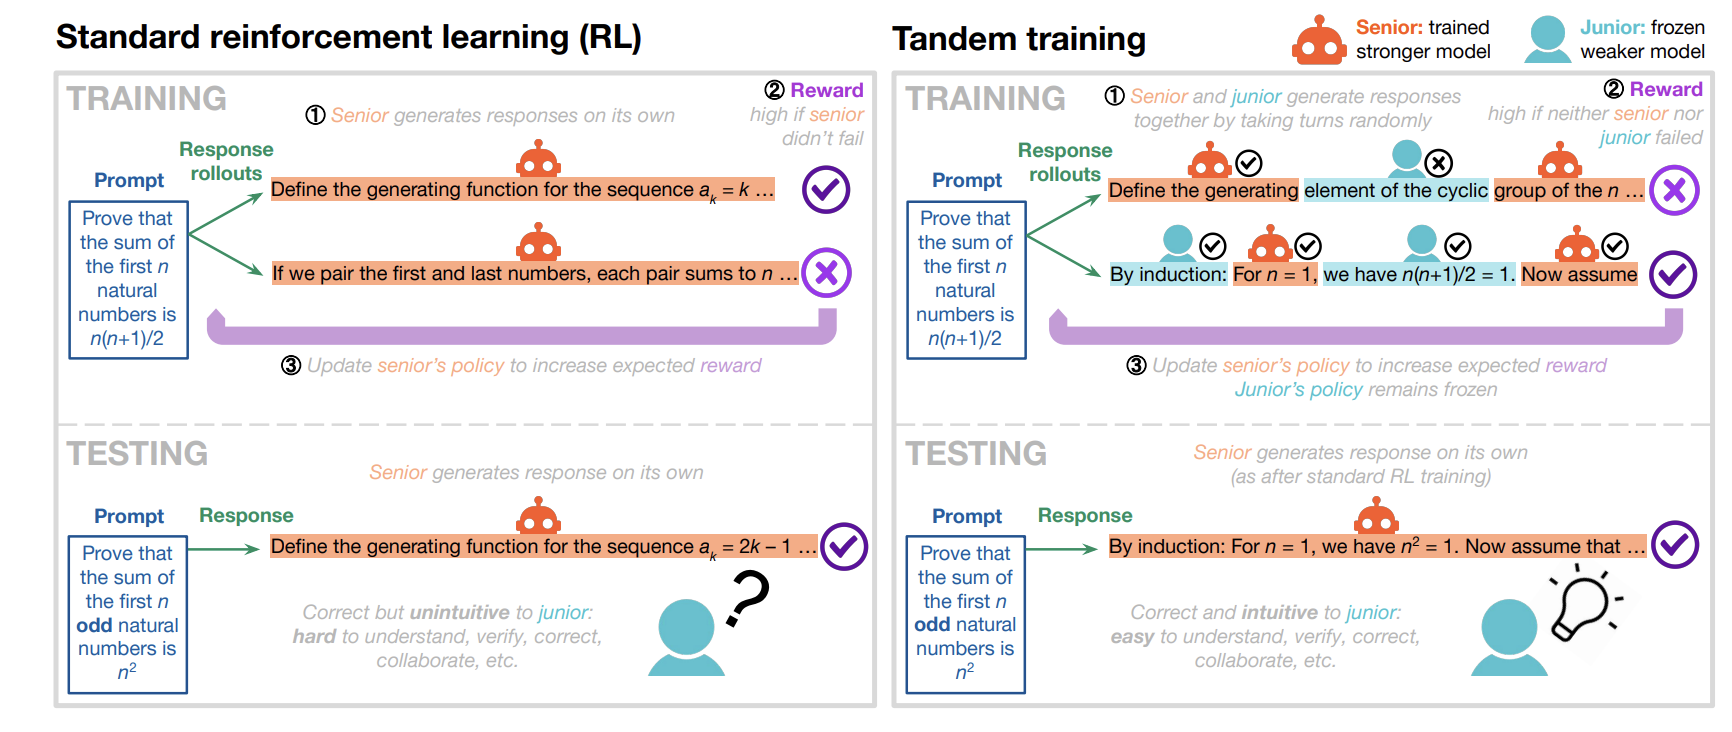
Do RL, except on the rollouts, on every word randomly (50%) let a frozen dumber model sample the next word instead of the smarter model actually being trained
- The idea is that this forces the smarter model to reason in a more legible, less jargony manner
- Having a more understandable reasoning output seems like a good thing. Not sure how this works with chain of thought models though.
Experiments
GSM8K, Llama-2-7B
“smarter” senior model = fine-tuned on GSM8k
also create some dumber junior model variants by prompting them with some few-shot examples to speak in a different language
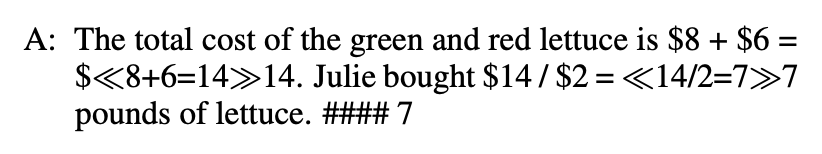
- GSM8k’s solutions involve repeating all arithmetic in « », which they call jargon (only the SFT’d model does it)
- they also call speaking in a language that the junior model doesn’t speak in “jargon”
For some reason they use REINFORCE (1 epoch) and discard negative rollouts instead of GRPO or something. Not sure why.
Results
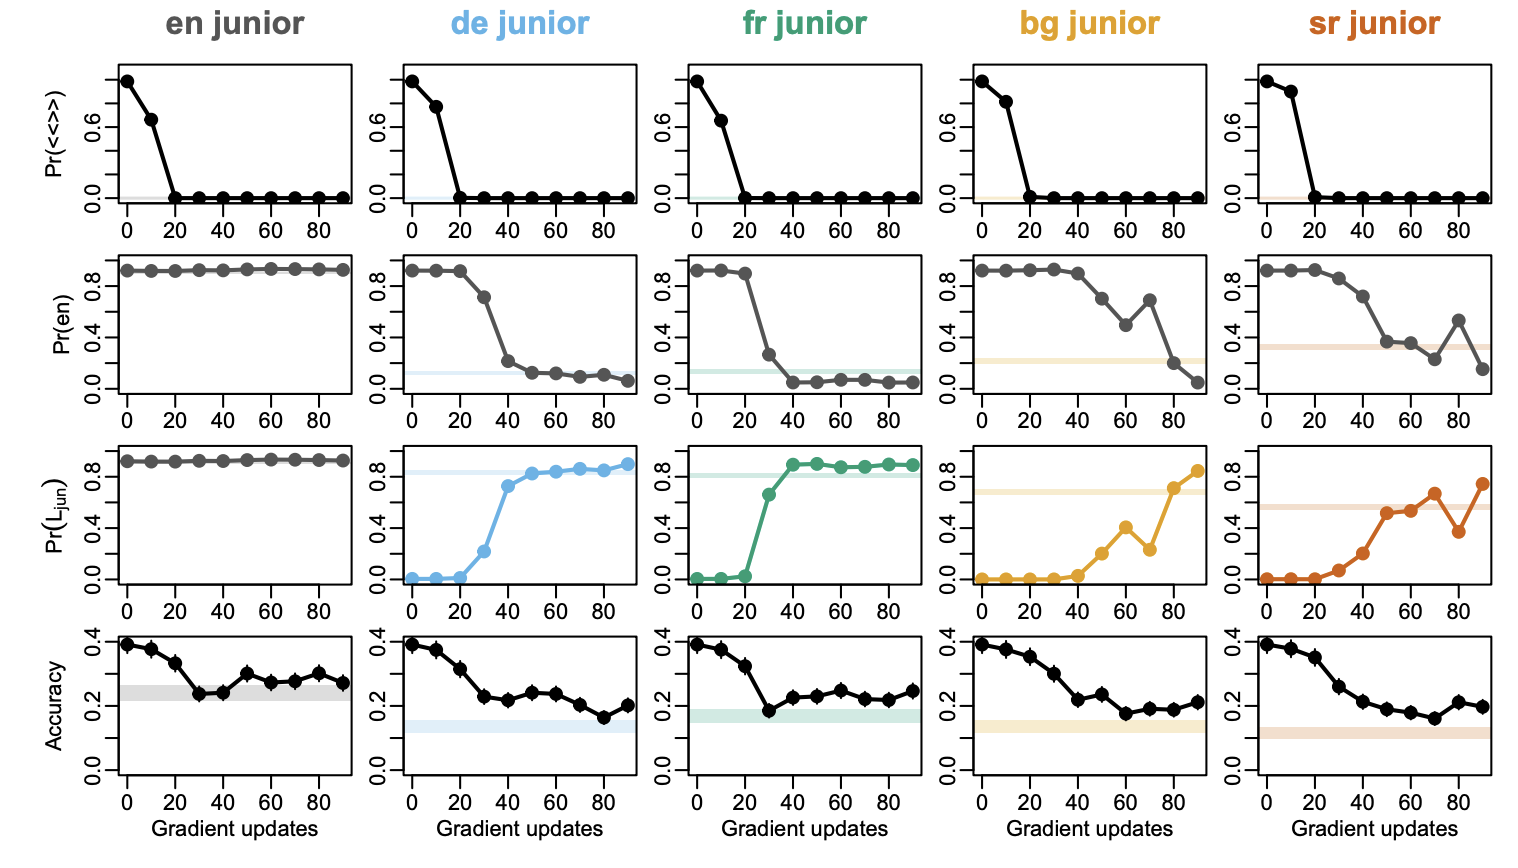
Accuracy does fall, but it remains a little higher than the dumber model.
The rate of jargon goes to zero, though, pretty quickly
They show that if you do some hyperparameter p-hacking on the reinforcement algorithm, you can keep accuracy up as well
Interestingly, if the senior and junior speak different foreign languages, the senior will try to use English as an intermediate language before giving up and using the junior’s language