Tandem Reinforcement Learning with Verifiable Rewards
Tandem RLVR
follow-up to tandem training
Tandem training using GRPO and initializing the senior and junior model to both be Qwen3-4B-Instruct-2507
- Unlike the tandem training paper, they finally only update on the senior-generated tokens from the rollout
Data: trained on DeepScaleR math, evaluated on AMC, AIME, Minerva, Olympiad (all math)
Results
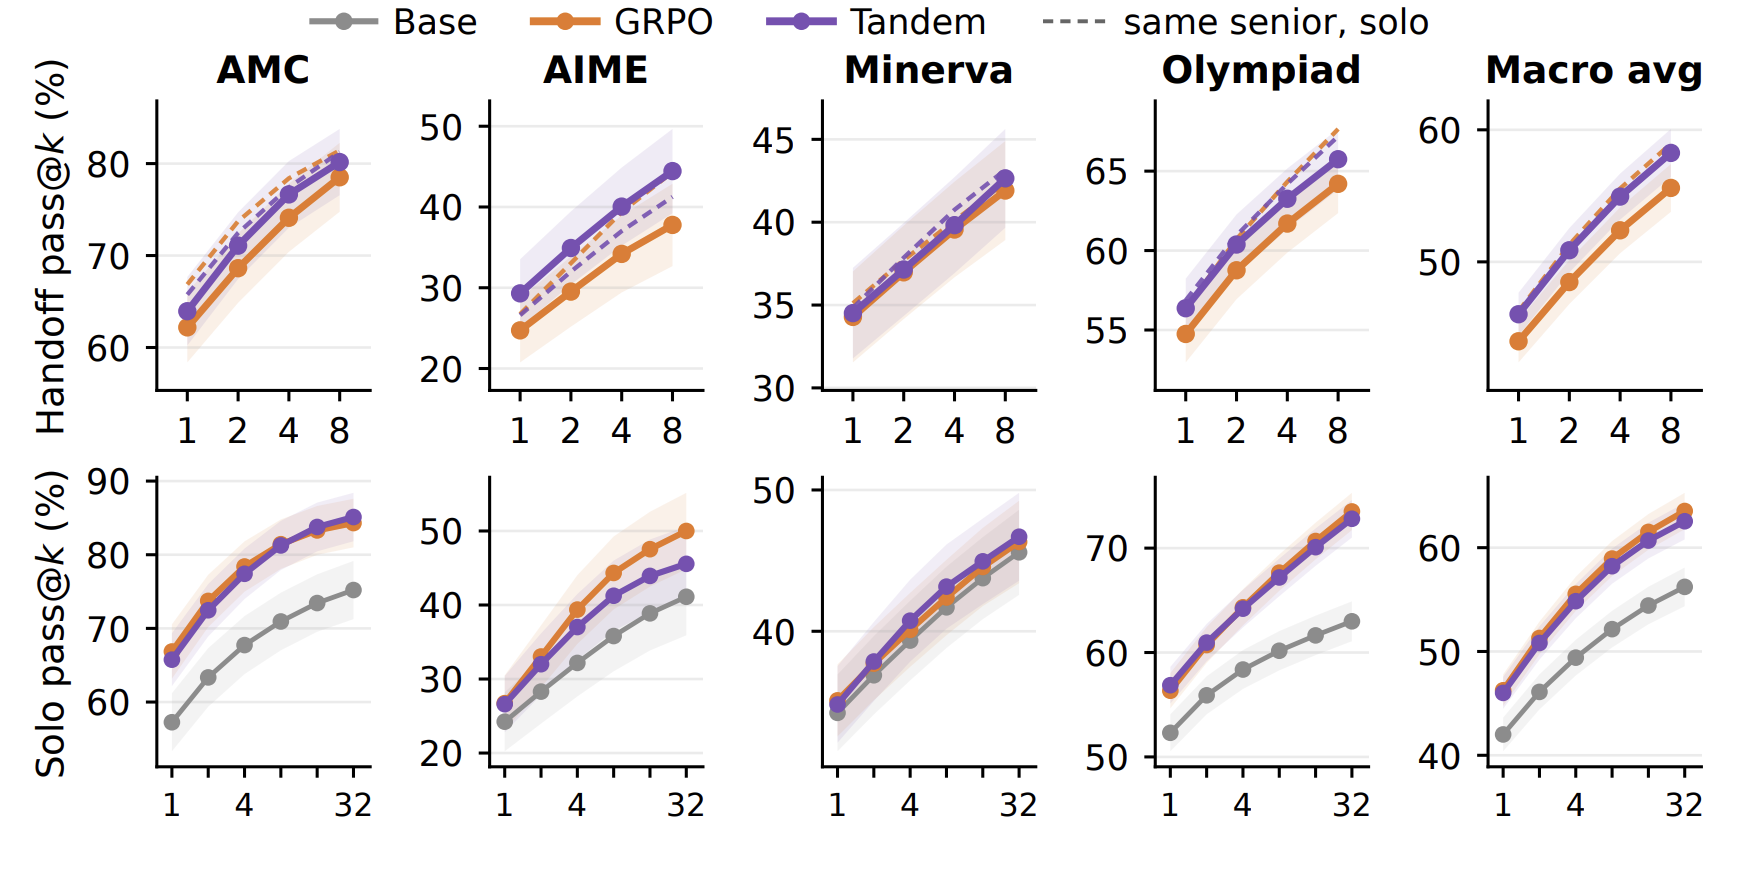
- pass@k with k as the x-axis
- Bottom row: When evaluated solo, the tandem trained model has approximately the same performance as the GRPO’d model
- Top row: When you hand off to the other model after every sentence (note that they’re trained to hand off every word, so this is a little bit generalization), tandem is a little better than GRPO
-
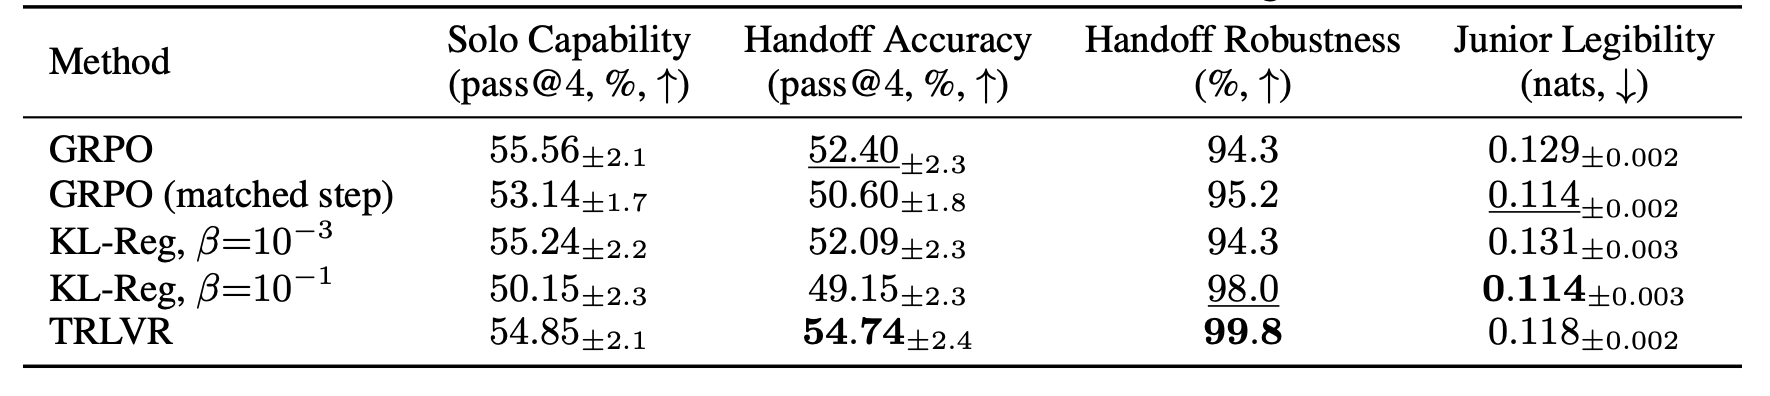
- TRLVR beats KL-regularization as a baseline
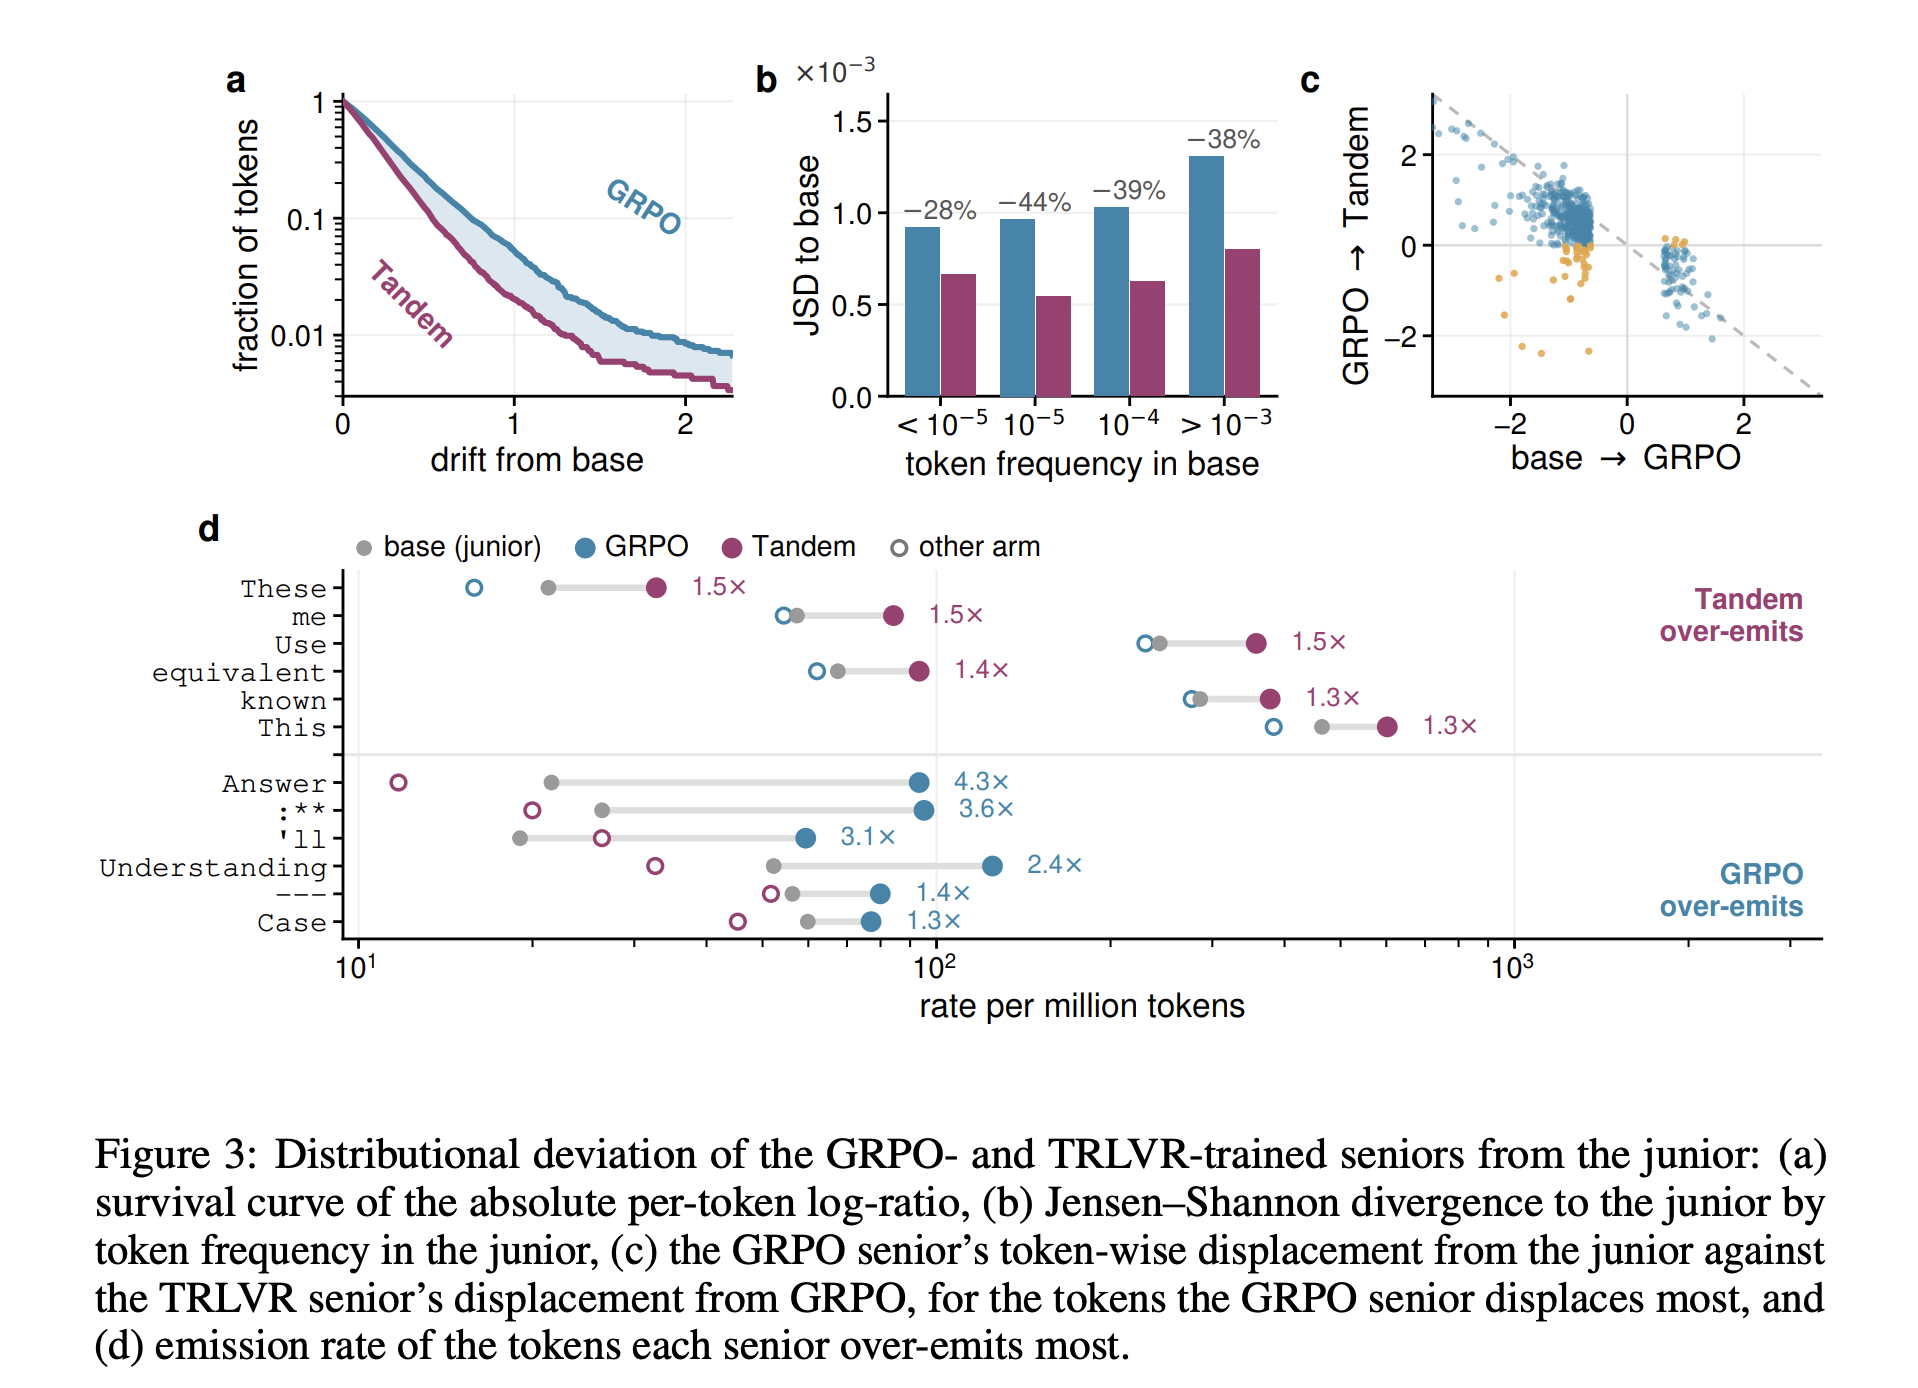
- A bunch of sketchy metrics showing that the distribution of tokens outputted by the tandem trained model is closer to the base model than GRPO.
- Seems that tandem gives more failure/transitioning words, and GRPO gives more formatting
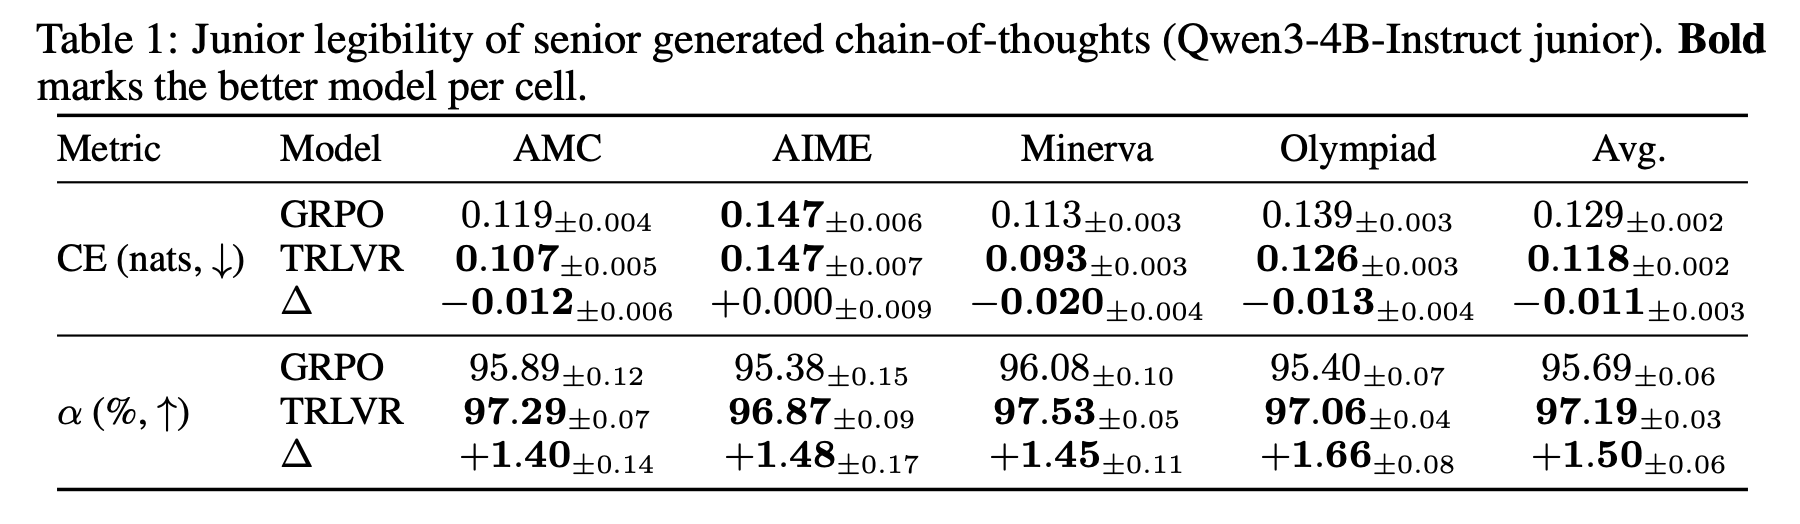
- The base model is less surprised about the words generated by the tandem model than the GRPO model
Implementation details
They had to fork vLLM because if you try to do the obvious thing of just using Hugging Face and manually managing the KV cache, it’s apparently too slow.
The best you can do is half the throughput, since you do need to always be generating both forward passes, since you need to maintain both KV caches
word boundaries are determined by tokens which began with a space, or by 32 tokens in a row, whichever one happens first
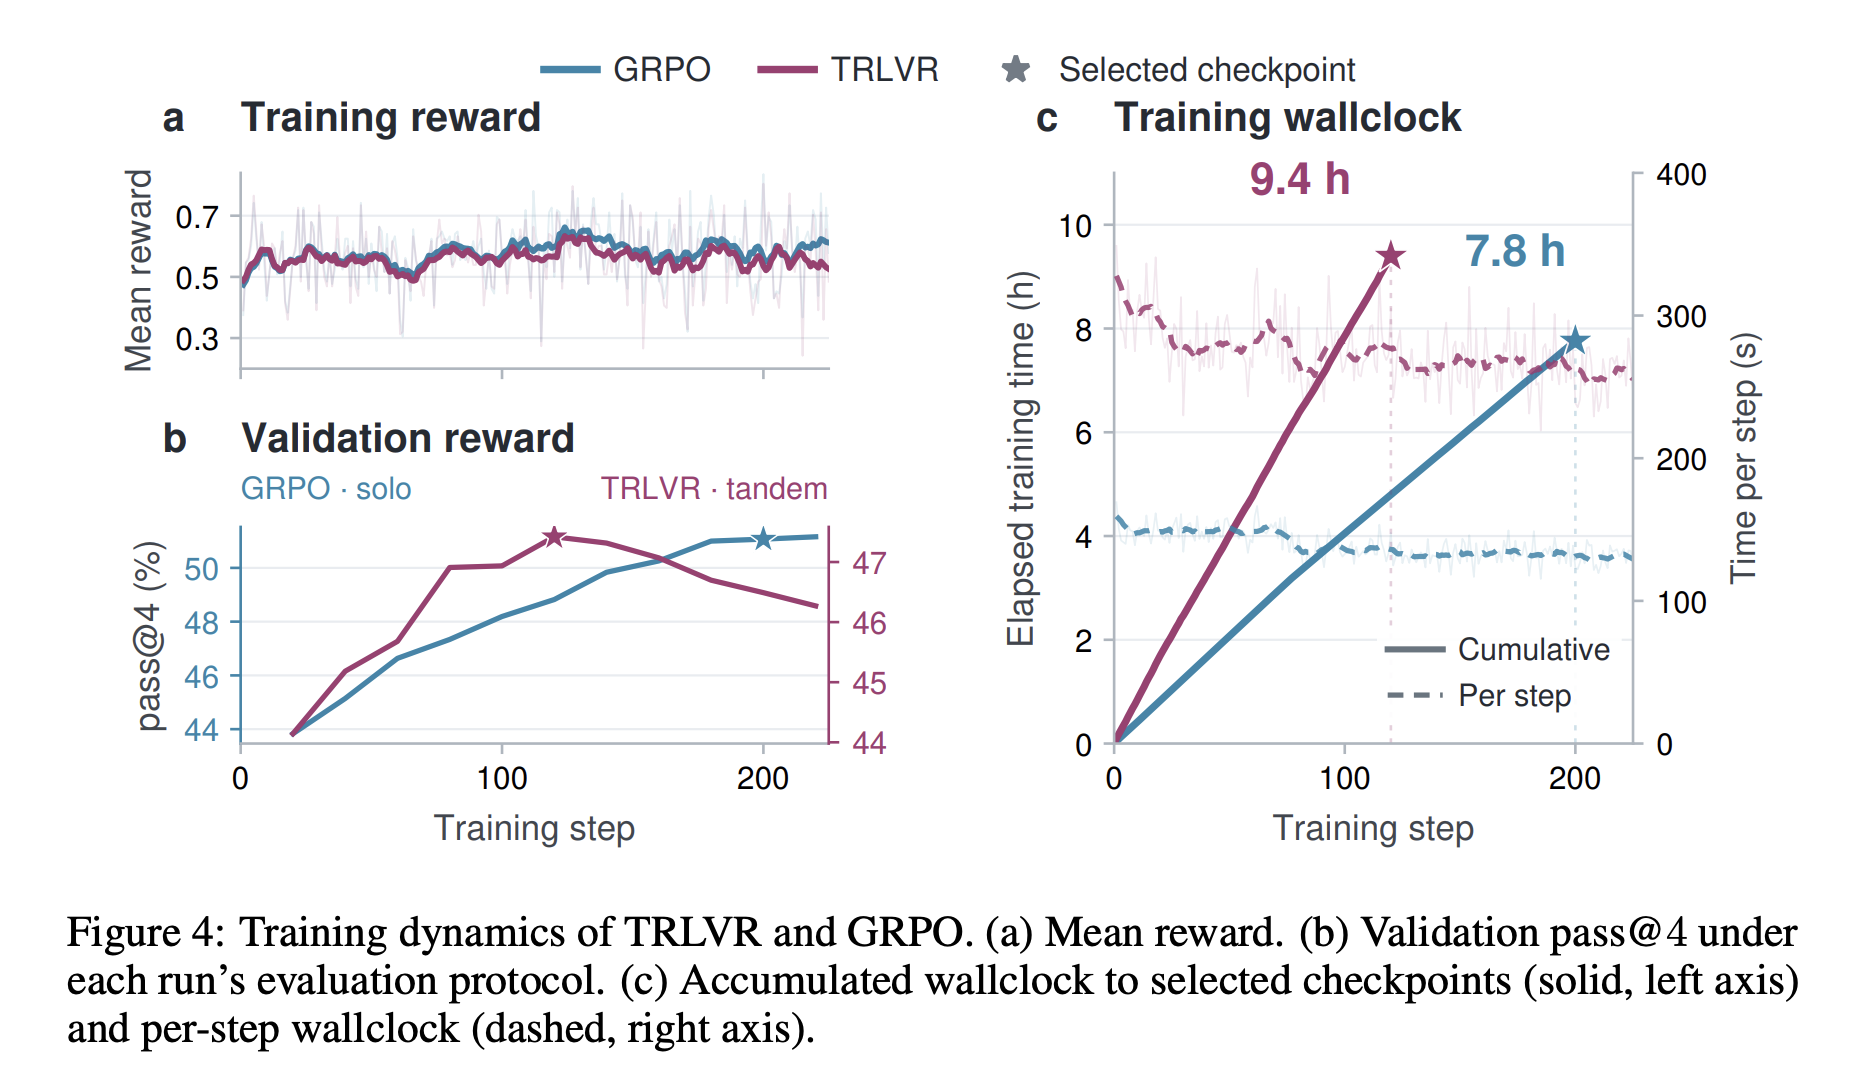
- training dynamics should look somewhat reasonable
Misc remarks
Their introduction has a few really nice points about the effect of RLVR on reasoning:
- https://arxiv.org/pdf/2603.22446 alibaba qwen shows that RLVR only really drastically changes the token distributions for a sparse set of tokens
- https://arcprize.org/blog/astra Astra created its own compact algebraic notation for solving ARC Agi 3
- https://arxiv.org/pdf/2608.09867 There are apparently some actual examples of obfuscated reasoning in the stolen chain of thoughts here