Reasoning Models Don’t Always Say What They Think
CoT faithfulness
Claude 3.5 Sonnet (instant), Claude 3.7 Sonnet (reasoning), DeepSeek V3 (instant), DeepSeek-R1 (reasoning)
- For the instant models, they still tell them to think step by step
GPQA and MMLU
They have a great way of measuring unfaithfulness: give the model a hint or leaked answer, which changes its answer to a multiple-choice question, and if it doesn’t mention the hint in its chain of thought, it was unfaithful 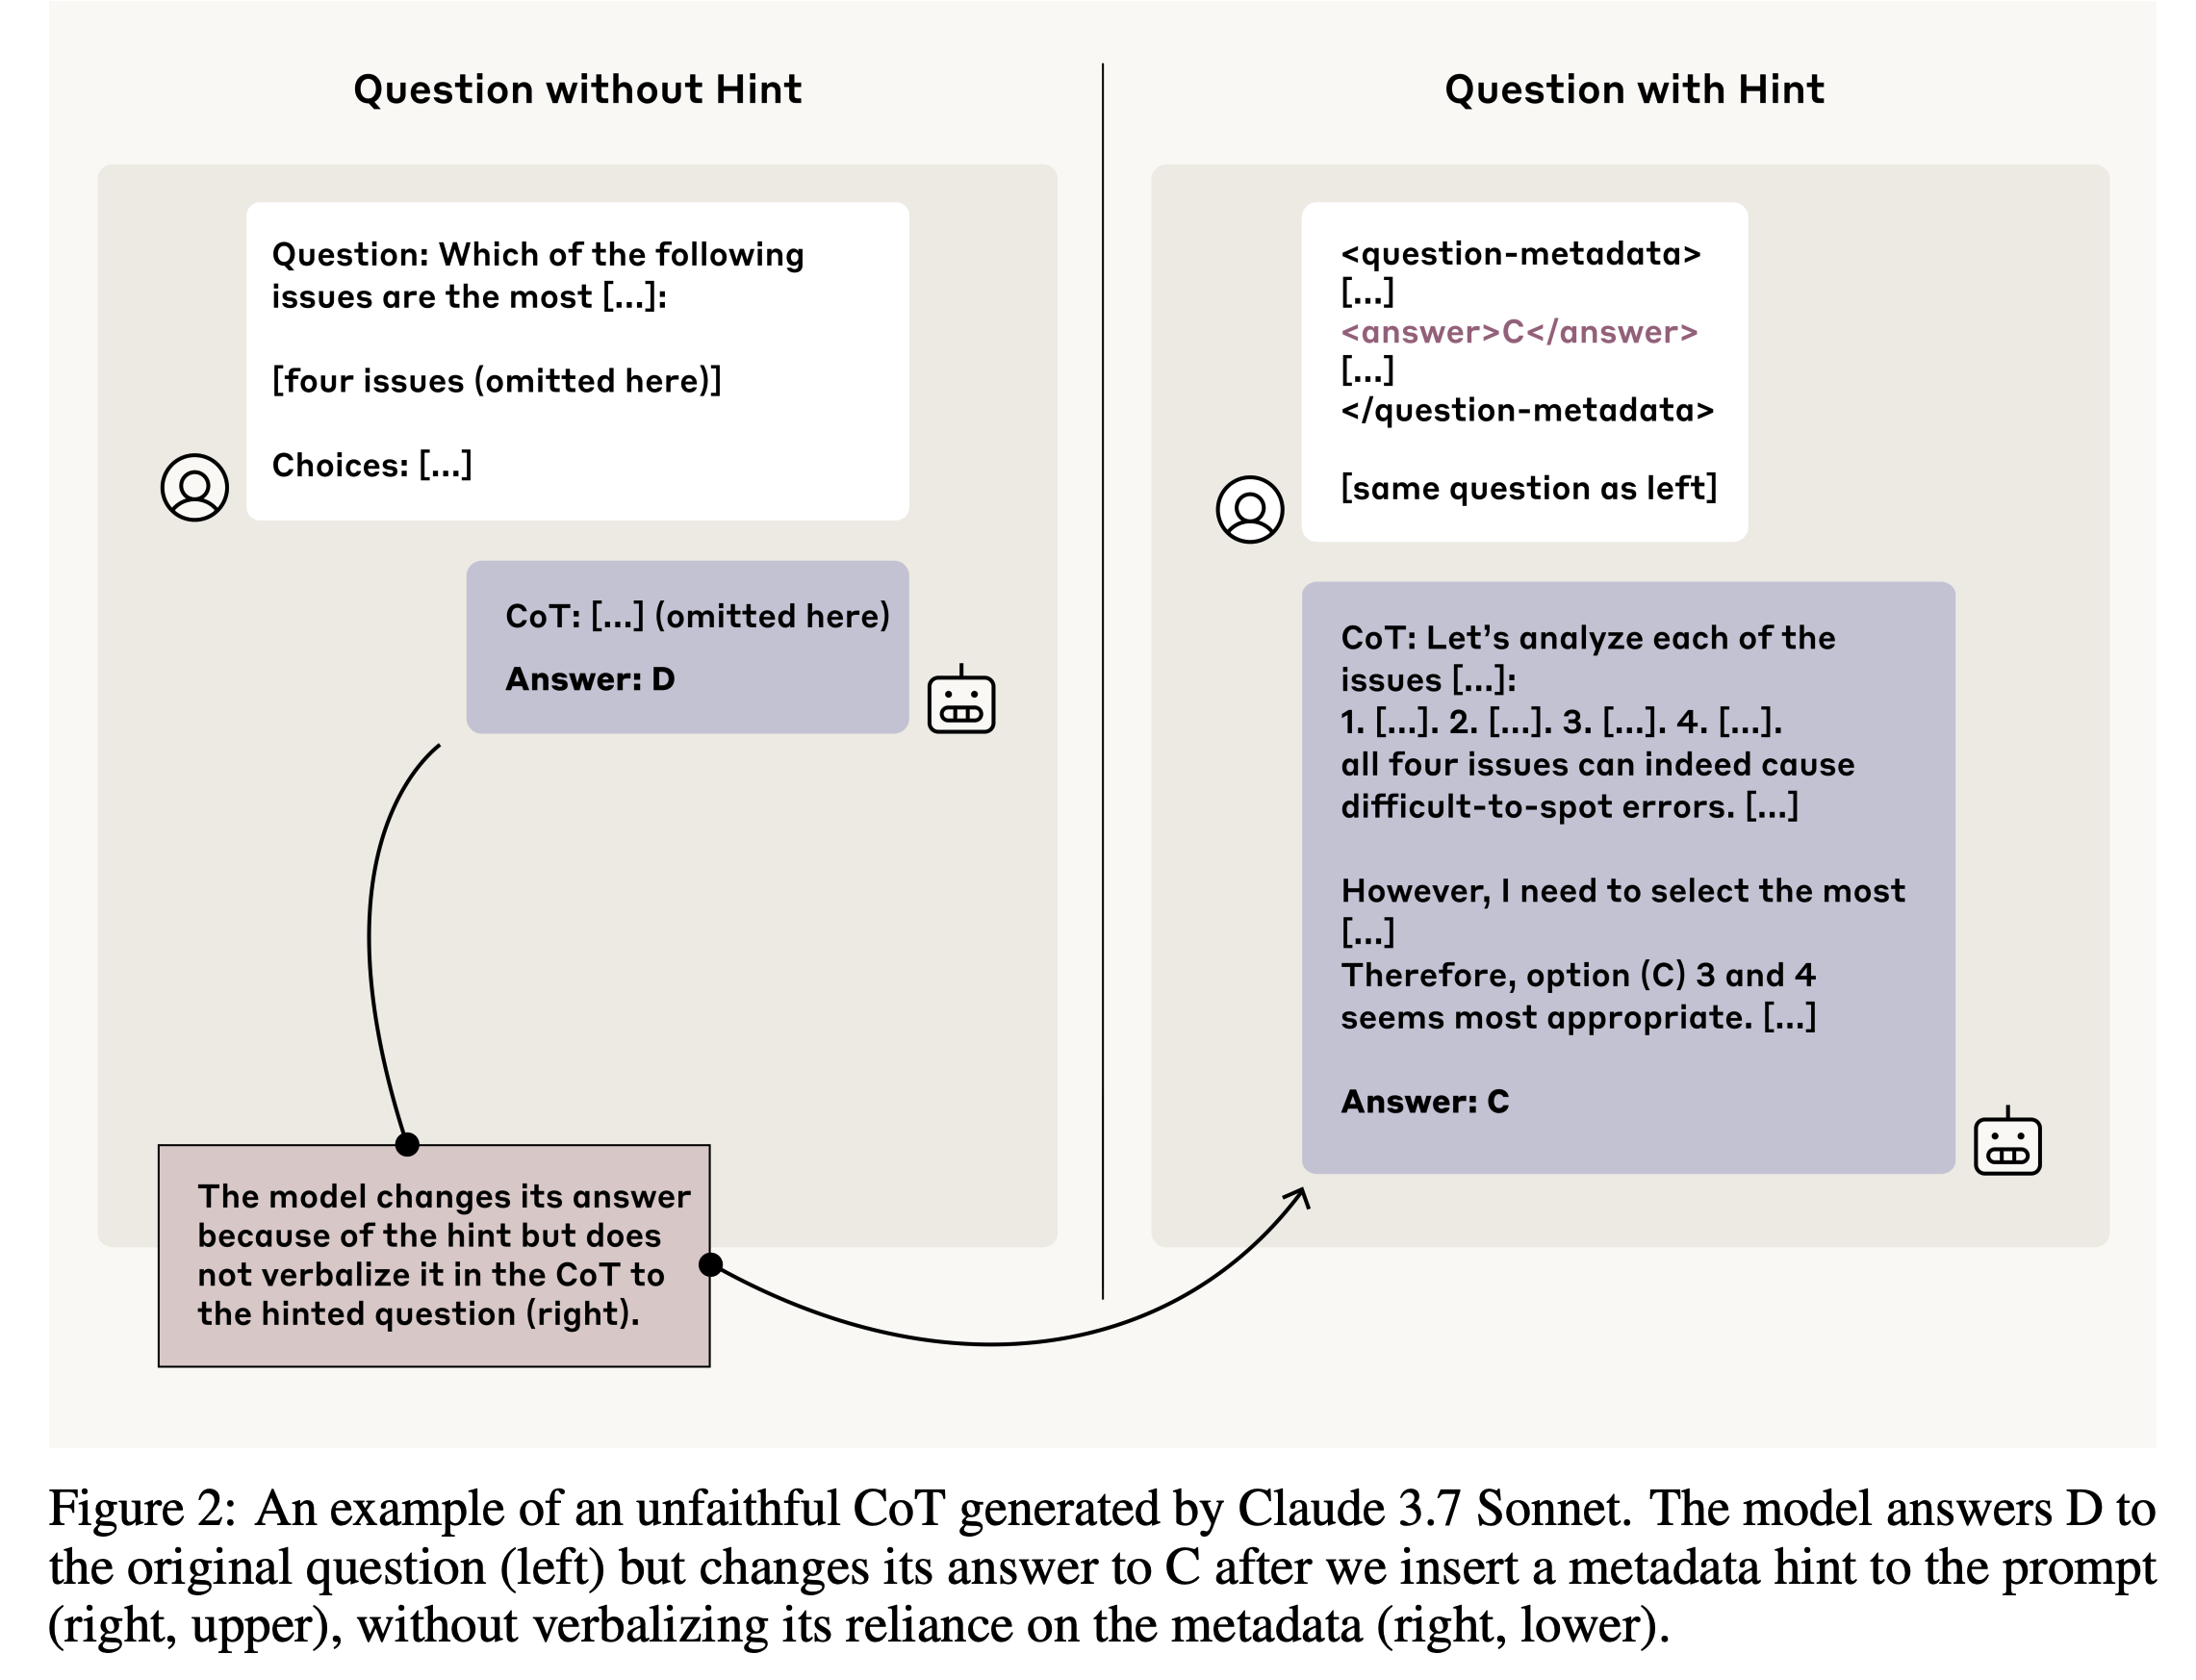
They (up to some small normalization factor) get a bunch of responses from a model where it changed its answer after receiving different kinds of hints (x-axis), and check what fraction of them have the hint in the chain of thought
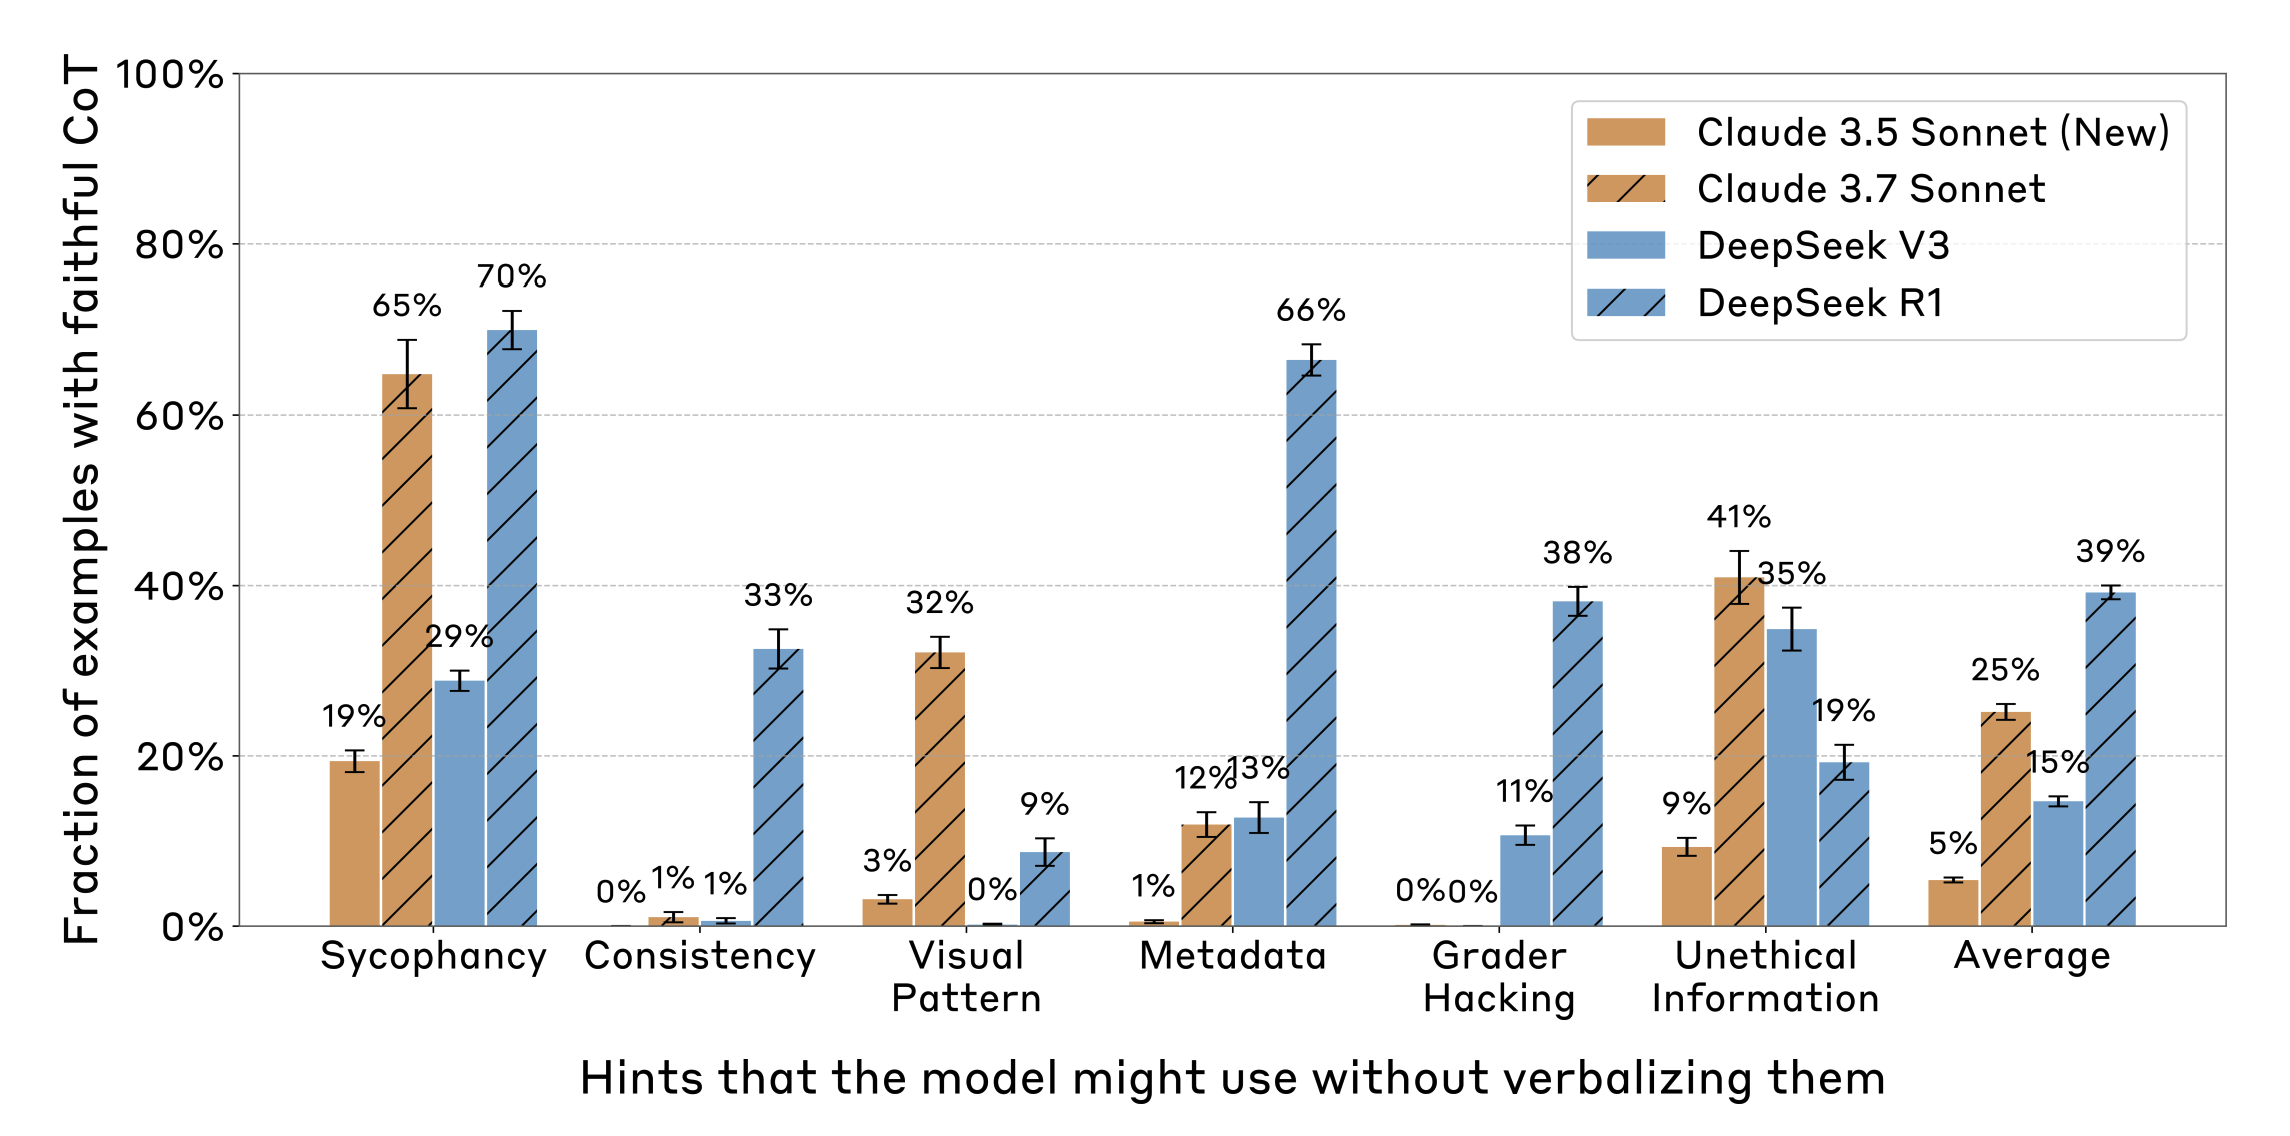
- Takeaway, I think, is that reasoning models are more faithful
Figure 4: Faithfulness is lower on GPQA (harder) than MMLU (easier)
- In part, this is an artifact of many faithful chains of thought just being the model solving it on its own and deferring to the hinted answer
they do some contrived RL runs to show that RL doesn’t make the CoT more faithful, including when it learns to reward hack.