On-Policy Distillation
Off-policy distillation (SFT) bad
On-policy training (normal RL) bad
Main weakness of on-policy distillation is that it needs a teacher model. Often this is a smarter model, though for things like mitigating forgetting it can be the original model.
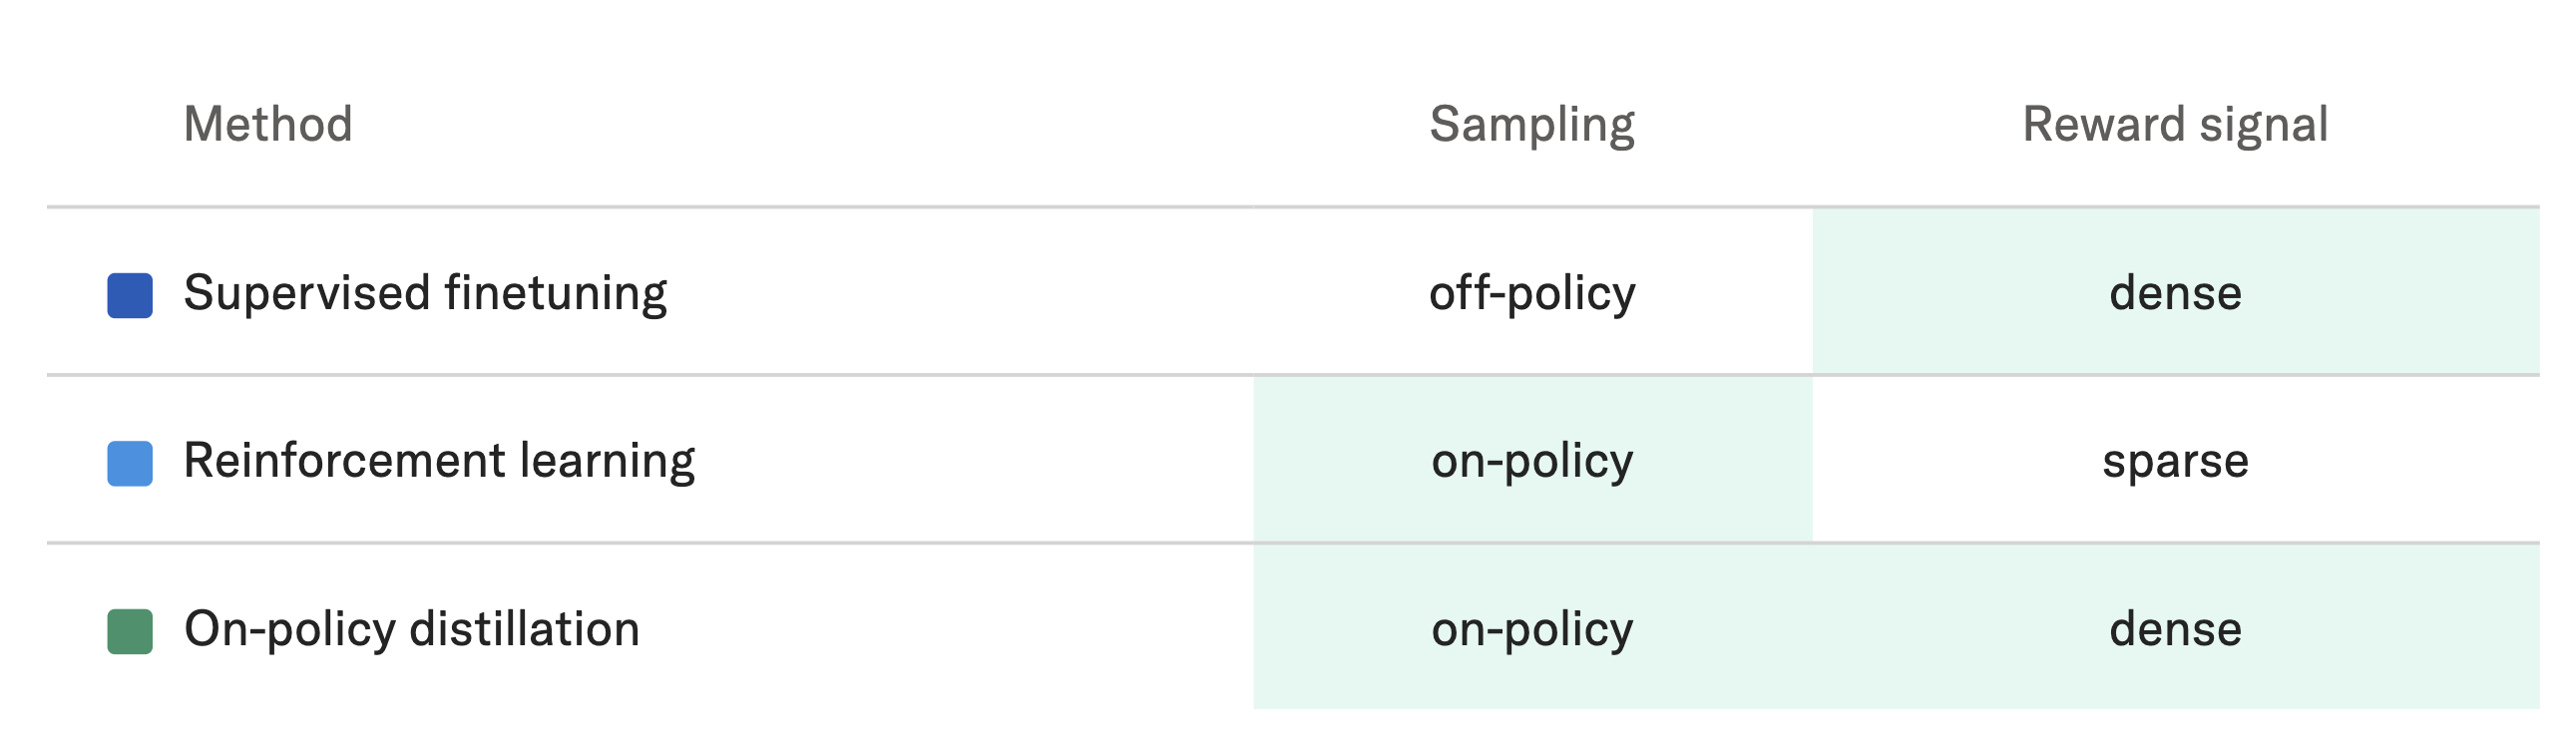
Sample from the student model (so that it’s on-policy) but grade each token’s log probs using the teacher model ($KL(\pi_\theta | \pi_{\mathrm{teacher}})$) , instead of just having one reward for the episode
and then just do RL with that reward
math training
The qwen paper itself uses on-policy distillation on top of SFT and normal RL
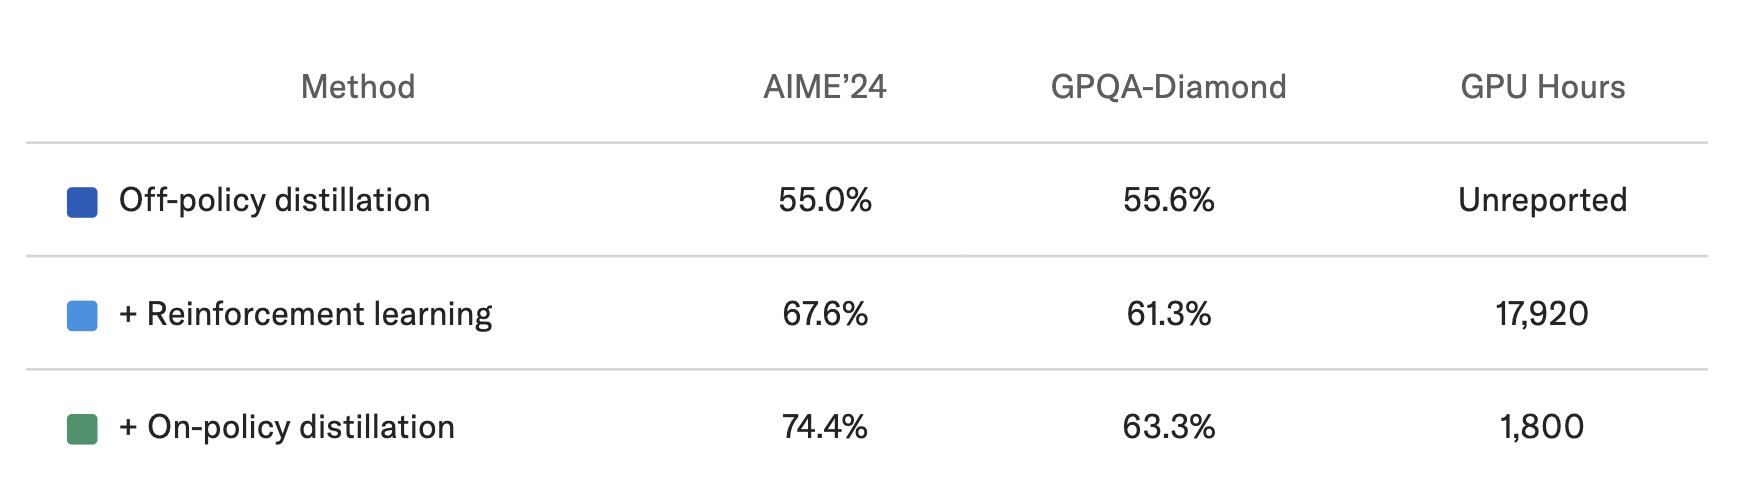
it seems that you can just do SFT + on-policy distillation and still do pretty well 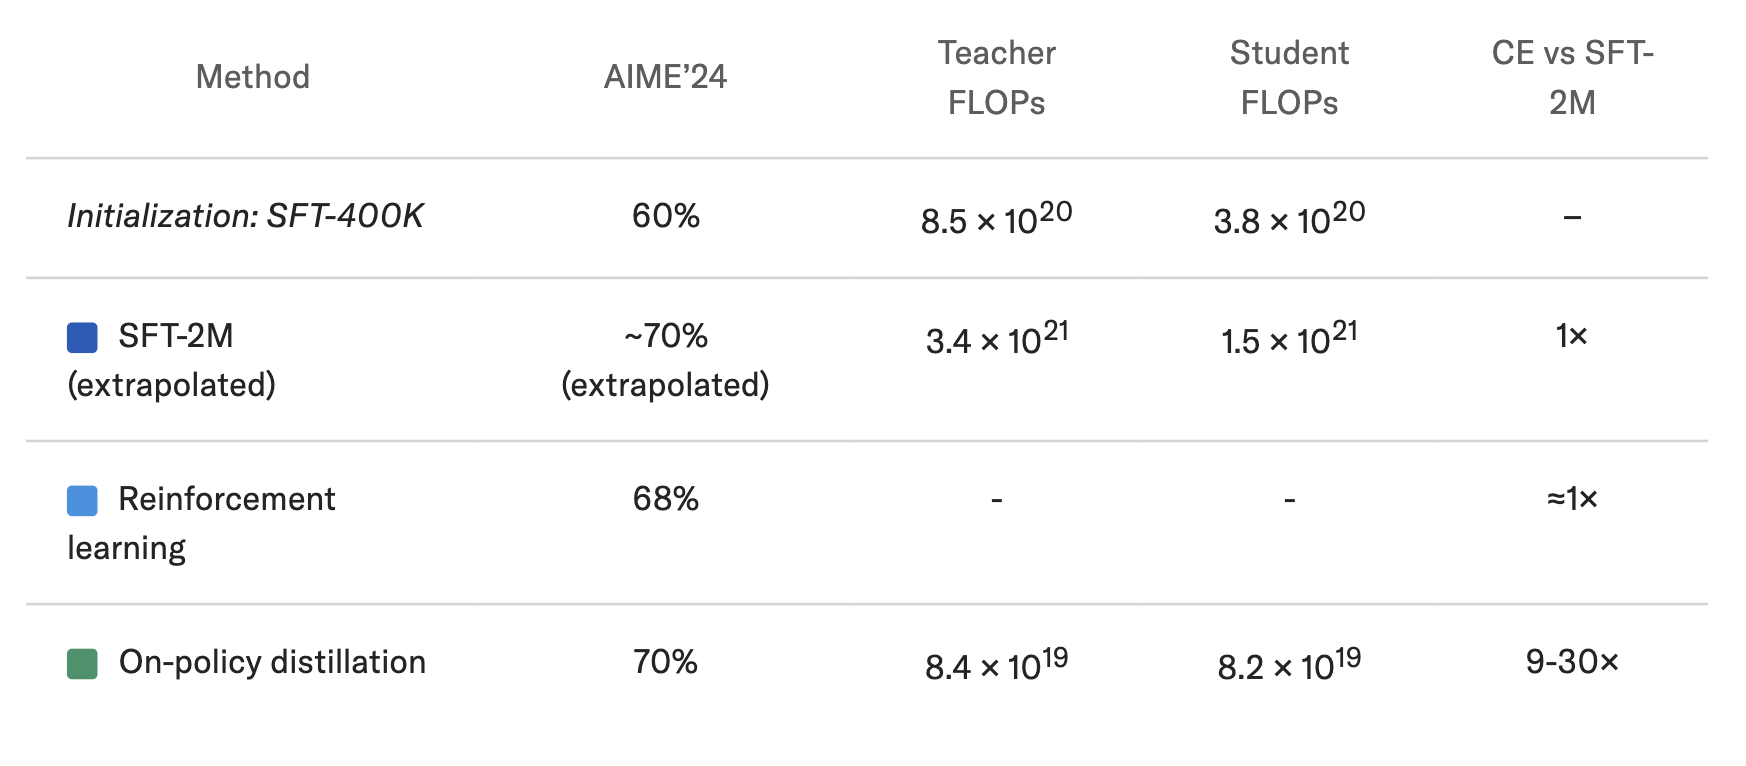
Personalization
Mid-training on internal company docs
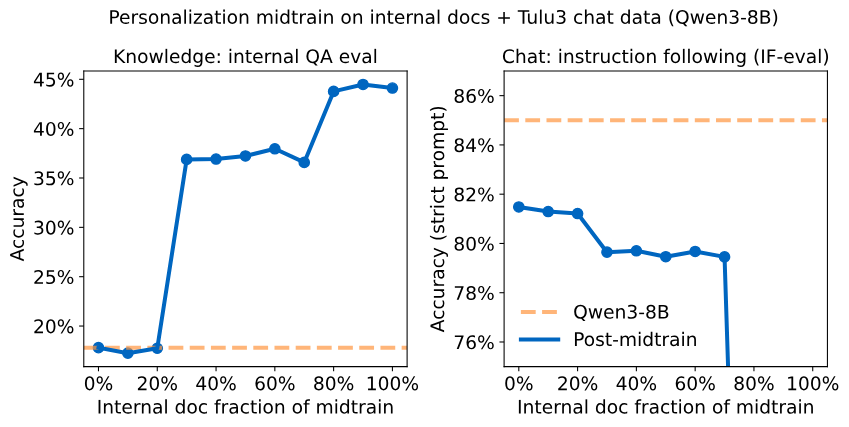
- even if you mix in original Qwen completions on Tulu3 (chat documents), SFT-alone still shows degradation on learned instruction following
On-policy distillation using the original Qwen as a teacher on Tulu3 mostly restores this forgotten capability 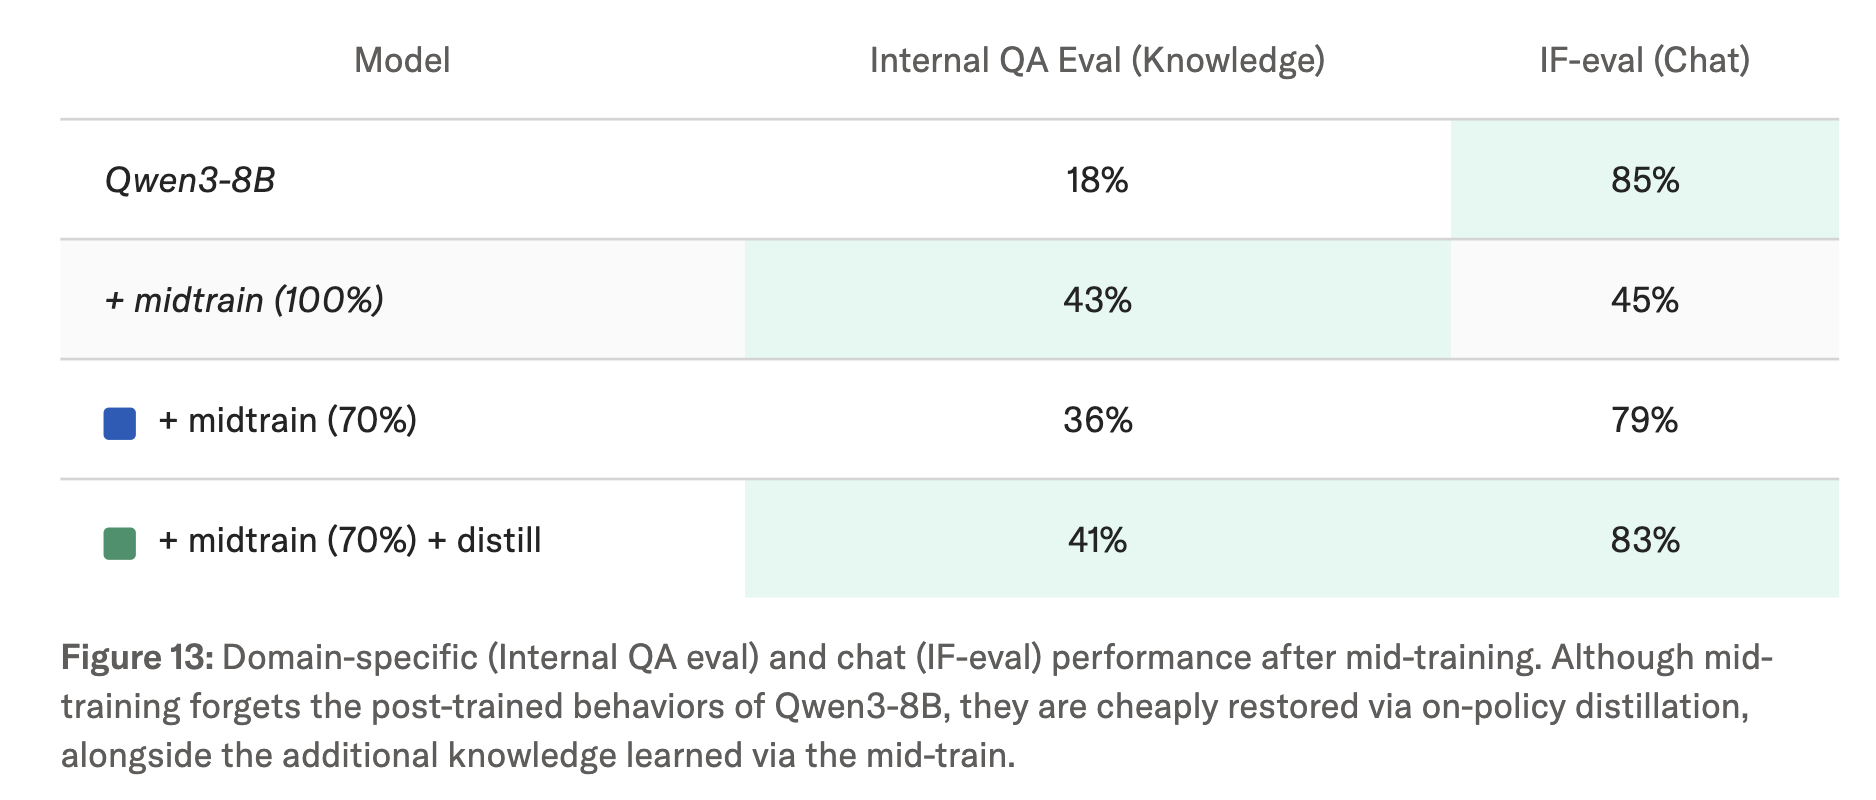
Discussion
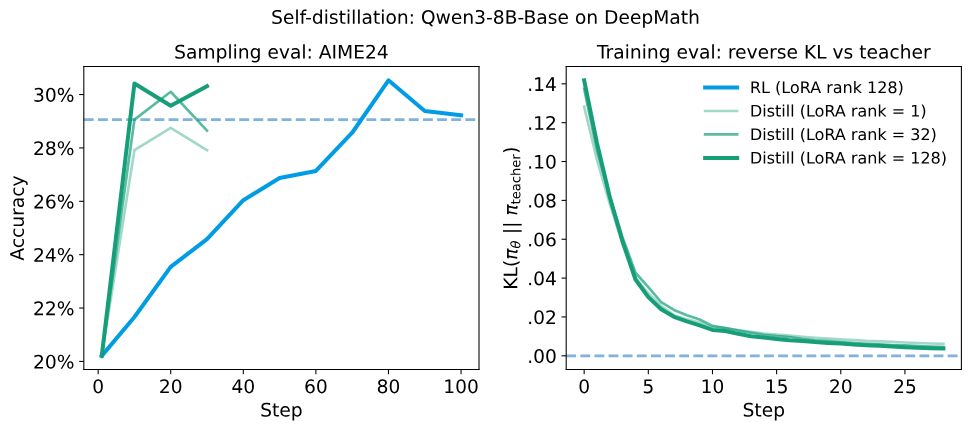
- denser reward than RL = more learning per gradient step
- RL is searching the space of strategies, but once you’ve found the good strategy, distillation gets you to learn it faster