Neural Cheat Sheets: Learning to Summarize with Reinforcement Learning
Neural Cheat Sheets
RL’ing models to summarize in short natural text, where those summaries are then used to answer downstream MCQ Q&A
Main takeaway for my project: graph with accuracy and length being the two axes might be good.
They tried two different rewards on the summary, supervised and unsupervised
unsupervised: reconstruction cross entropy loss on the original document with vs without the summary, ish 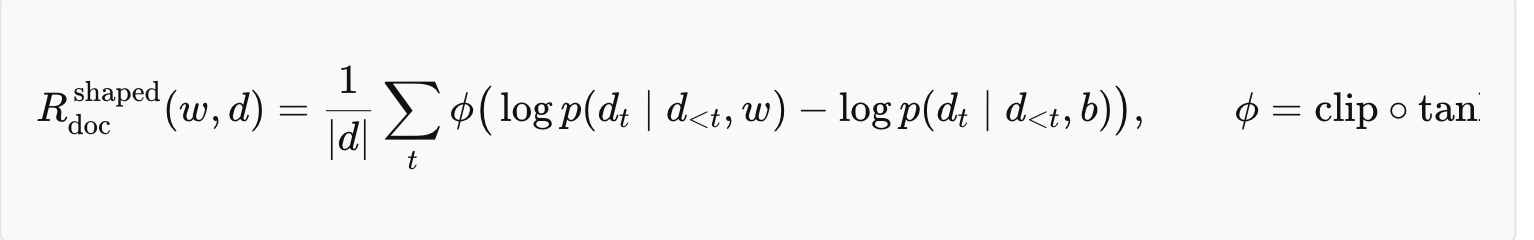
- You have to include a concave function on this, otherwise, the model learns to just copy the text directly, since that greatly decreases perplexity on the copied tokens and leaves everything else mostly unchanged
supervised: using the downstream QA directly
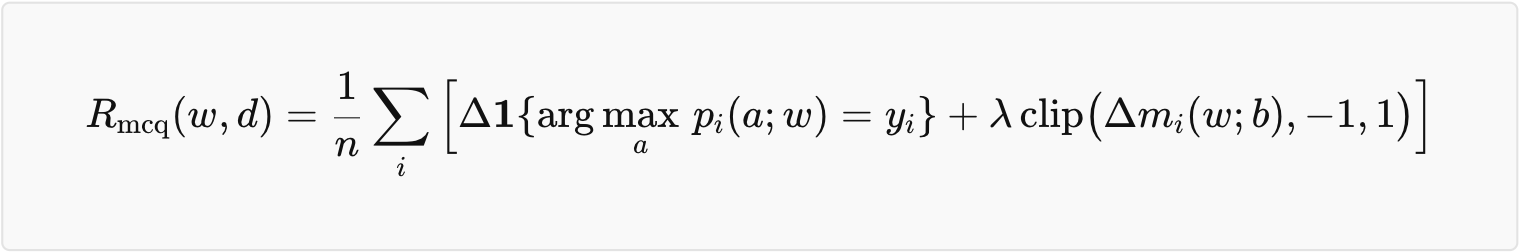
- To get a denser reward signal, you can reward when the model has the higher gap over the second best answer
Experiments
Qwen3-4B, QuALITY (short stories), QASPER (NLP research papers), LongHealth (patient health records)
Results
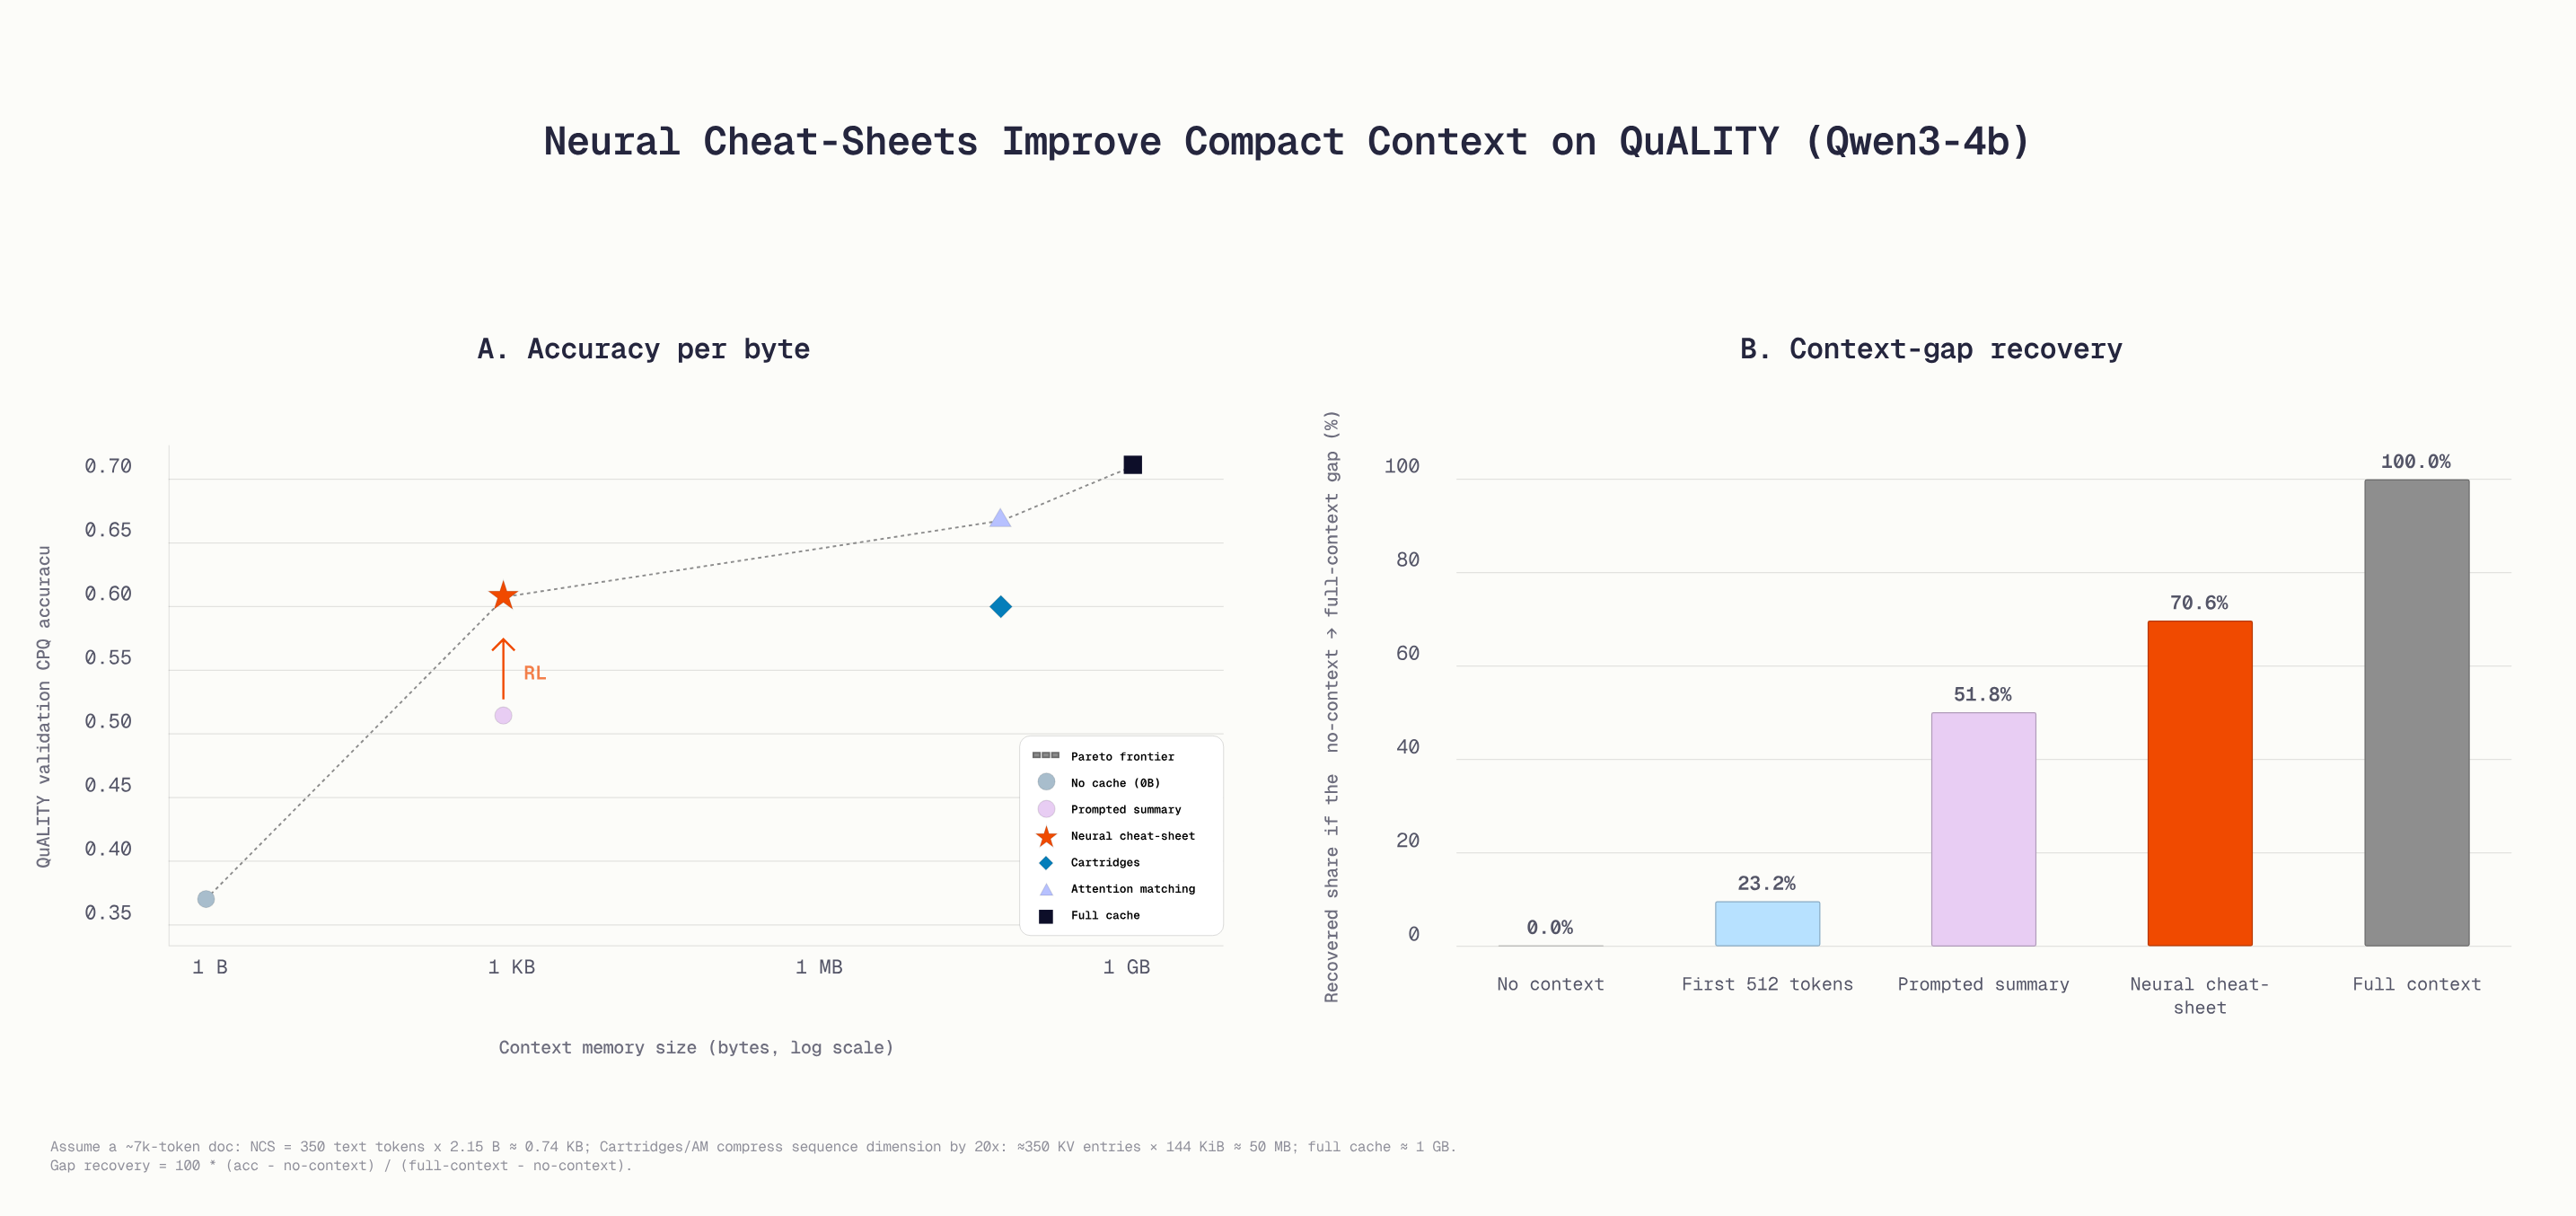
- I think we could make this graph, with size of the context vs accuracy compared to some other methods maybe (though we’re not directly apples-to-apples since we’re not doing summarization, though it somewhat can still hold)
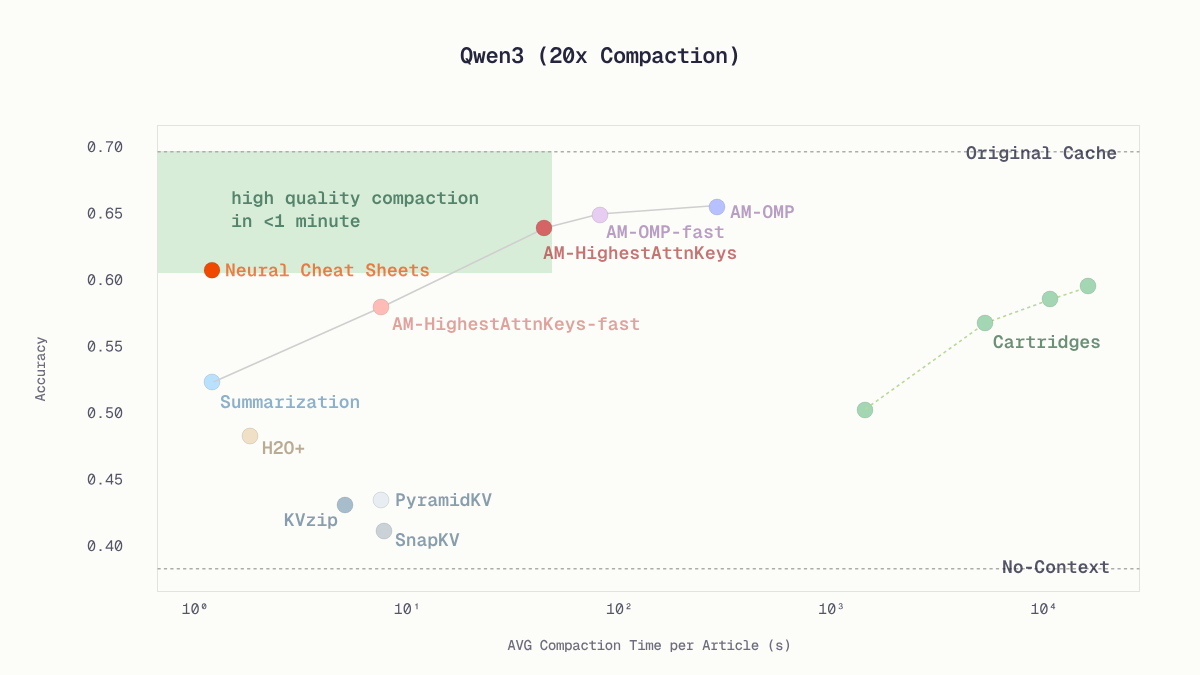
- this would just be misleading for us, as we’re not compaction
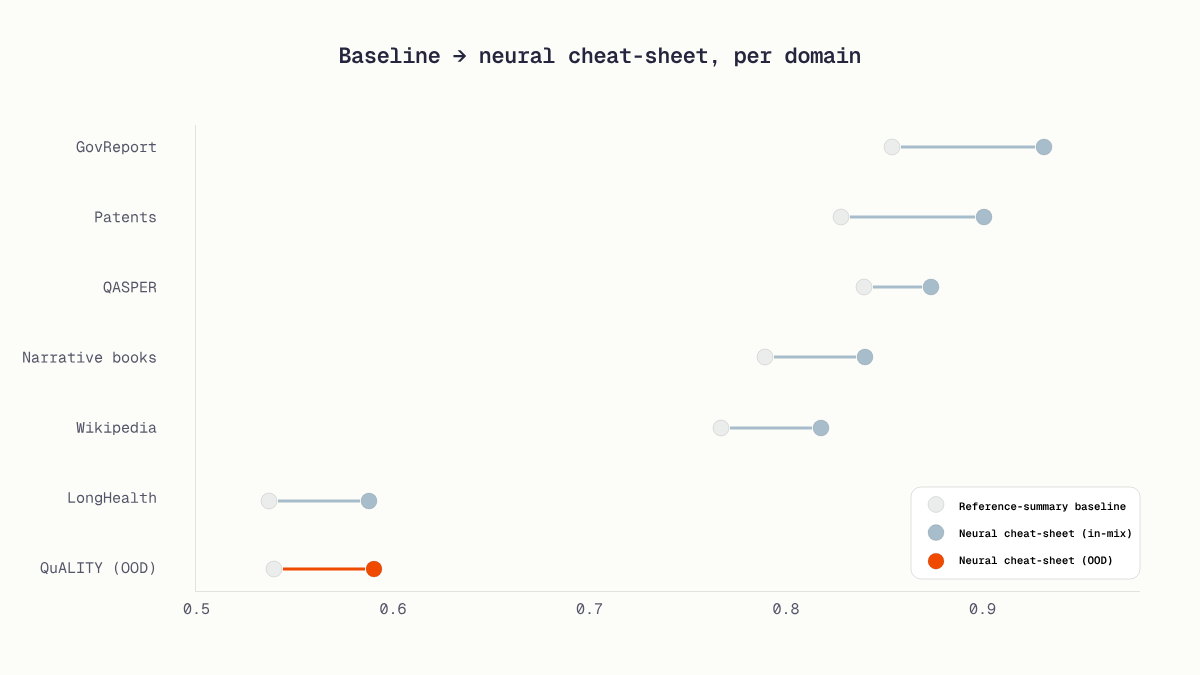
- good generalization test, train on a bunch of summarization tasks and it boosts summarization performance for held-out domain, as much as if you trained on it directly. We can do similar generalization tests.