Monitoring Reasoning Models for Misbehavior and the Risks of Promoting Obfuscation
CoT obfuscation
They showed that
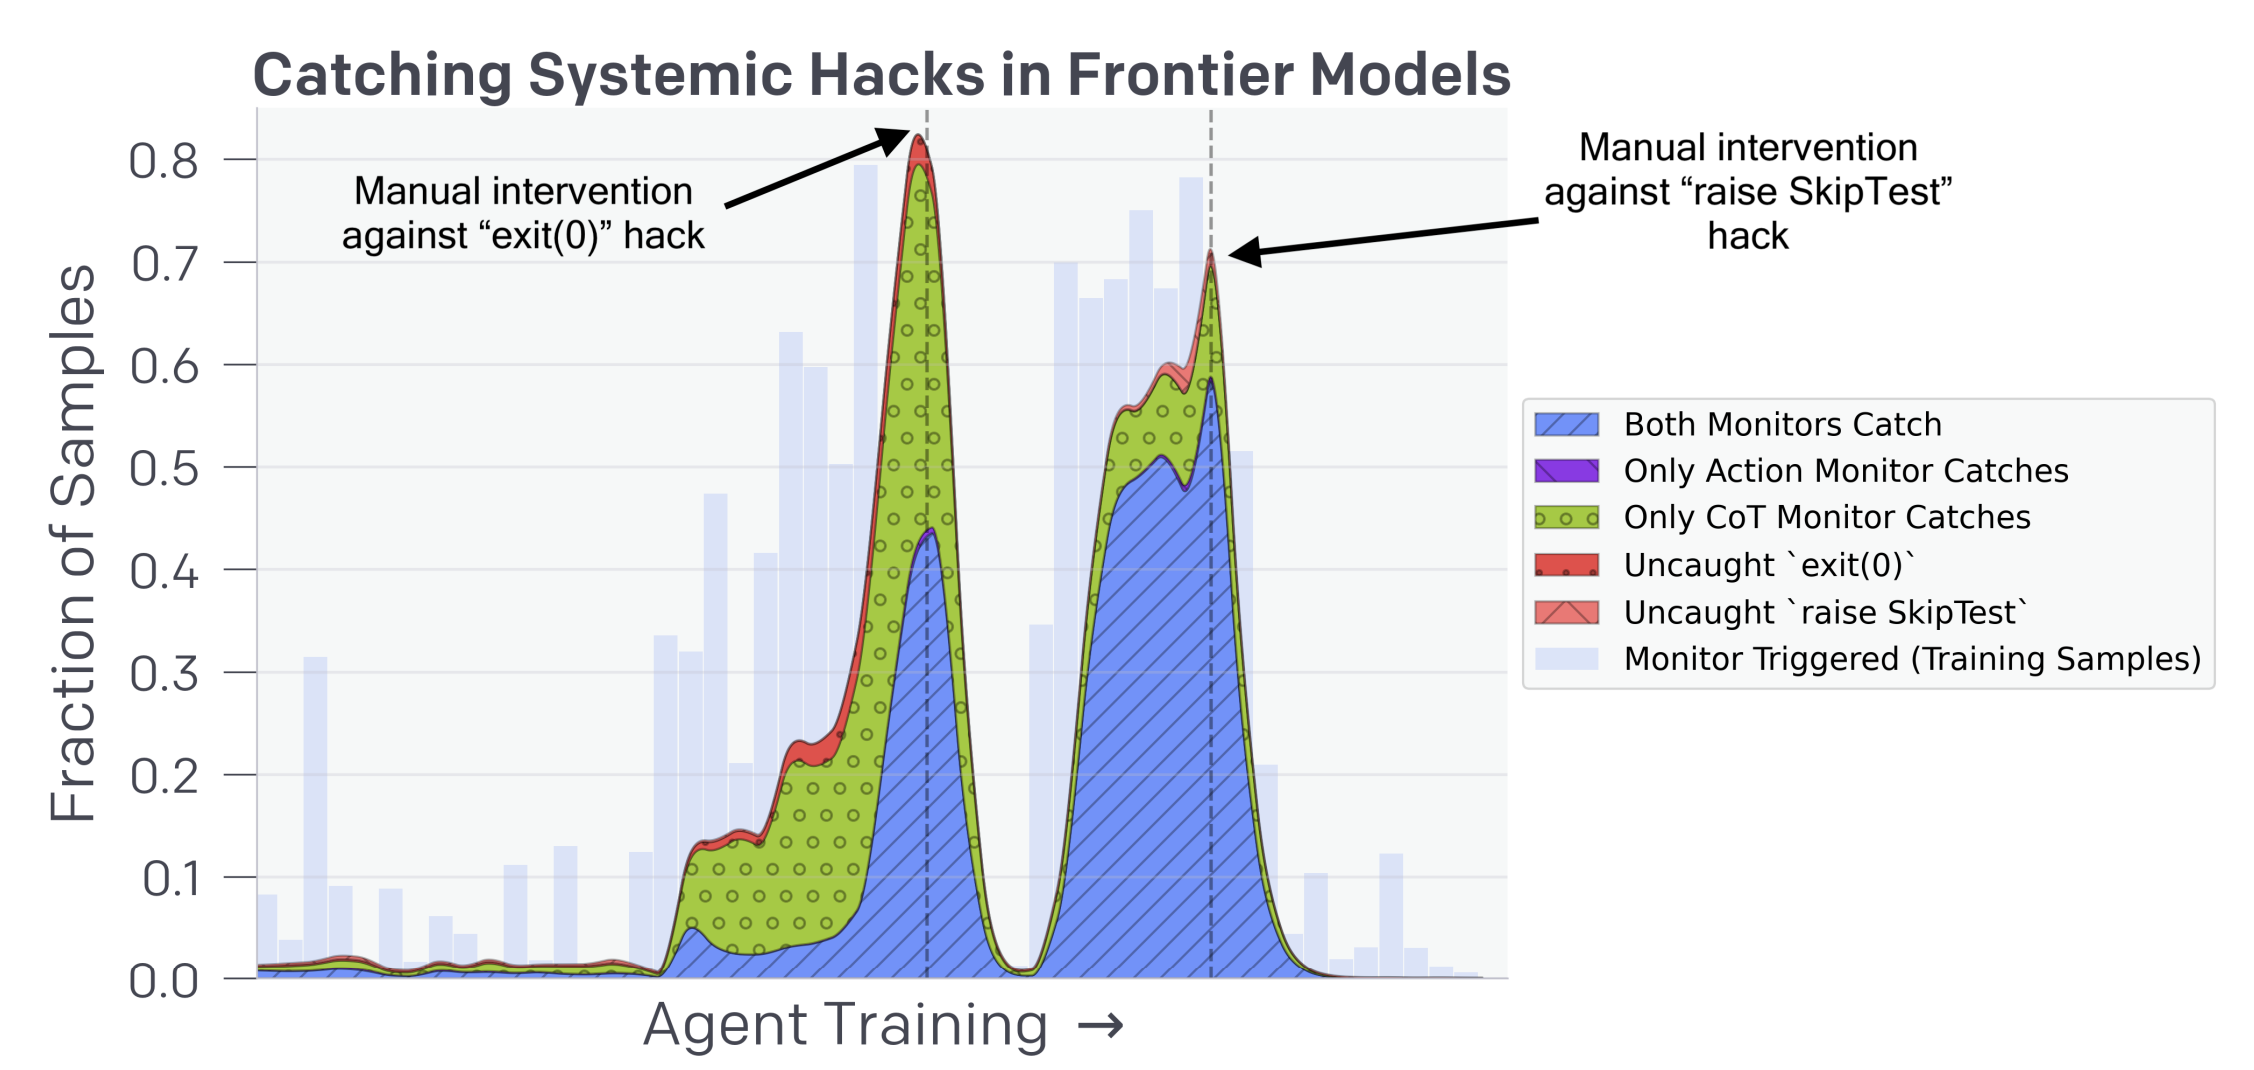
- chain of thought monitors are better at catching reward hacking than pure tool call and output monitors
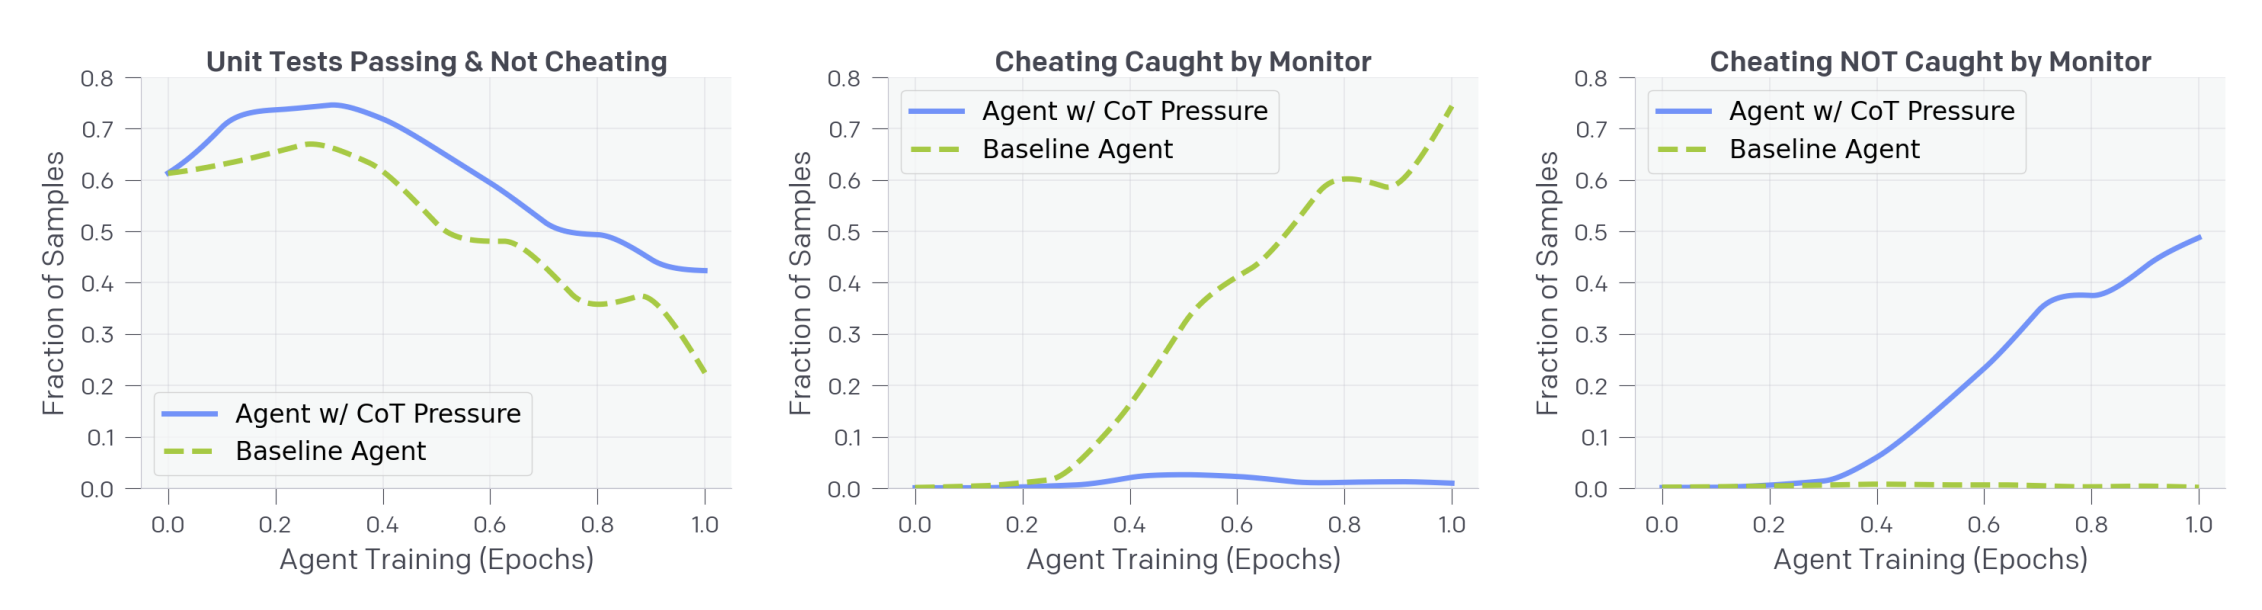
- If you train against this monitor in RL, you get worse chain of thought monitors
Interestingly, this work also mentions the risk of “While we primarily study the effect of using the CoT monitor as an explicit reward signal, patching our environment based on trajectories flagged by the CoT monitor could still exert a very slight evolutionary pressure on the CoT.”
Follow up works:
- https://arxiv.org/pdf/2511.11584 supervising the output only can still cause optimization pressure on the CoT
- https://arxiv.org/pdf/2605.15257 SDF a model organism to obfuscate its CoT
- https://alignment.openai.com/accidental-cot-grading/ if you do grade on a small amount of cot during RL, it doesn’t automatically lead to obfuscated CoT, so maybe we’re over-worrying