Modular Manifolds
written by the author of deriving Muon
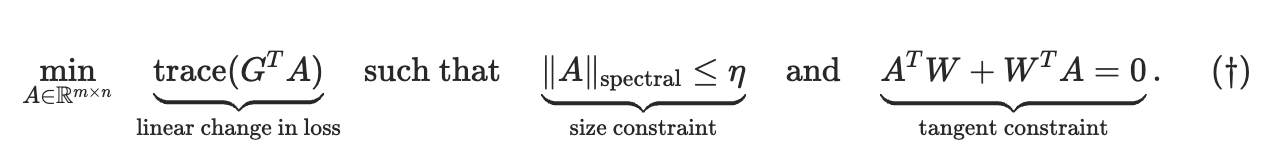
Instead of forcing the gradient update to be all singular-values 1, what if you instead keep the weights on a manifold of all singular-values 1, and make the update steps tangent to that manifold and project back down to it?
And modular manifolds is the idea that you can choose a different manifold and norm for each layer, and compose them with the composed manifold just being their cartesian product, and the composed norm being the max of the individual norms, and theoretically figure out what the individual learning rates for each layer should be